
Detect and Annotate
Detect objects and annotate boxes, labels, or masks with RF-DETR, YOLO, or your
preferred detection or segmentation model using Supervision and ml-pipes.
The examples use RF-DETR through
Roboflow Inference.
Run Detection
First, you'll need to obtain predictions from your object detection or segmentation model.
To run inference, initialize a Roboflow Inference model and pass it the source
image. The result is an Inference response object that you will convert to a
Detections instance in the next step.
from ml_pipes.core import Pipeline
from ml_pipes.supervision import ImageToArray
from ml_pipes.supervision.inference import RoboflowInference
from ml_pipes.vision import Decode, LoadFile

pipeline = Pipeline(
    [
        LoadFile(),
        Decode(),
        ImageToArray(),
        RoboflowInference(model_id="rfdetr-small"),
    ]
)

results = pipeline("people-walking.jpg")
Load Predictions into Supervision
Now that we have predictions from a model, we can load them into Supervision.
Supervision's converters turn model predictions into a unified Detections
object for filtering and annotation, regardless of the model that produced them.
from ml_pipes.core import Pipeline
from ml_pipes.standard import Select
from ml_pipes.supervision import Detections, ImageToArray
from ml_pipes.supervision.inference import RoboflowInference
from ml_pipes.vision import Decode, LoadFile

pipeline = Pipeline(
    [
        LoadFile(),
        Decode(),
        ImageToArray(),
        RoboflowInference(model_id="rfdetr-small"),
        Select(0),
        Detections.FromInference(),
    ]
)

detections = pipeline("people-walking.jpg")
Use the sv.Detections.from_inference method, which accepts model results from both detection and segmentation models.
The available operators for loading predictions from other frameworks are listed under Detection Boundaries.
Annotate Image with Detections
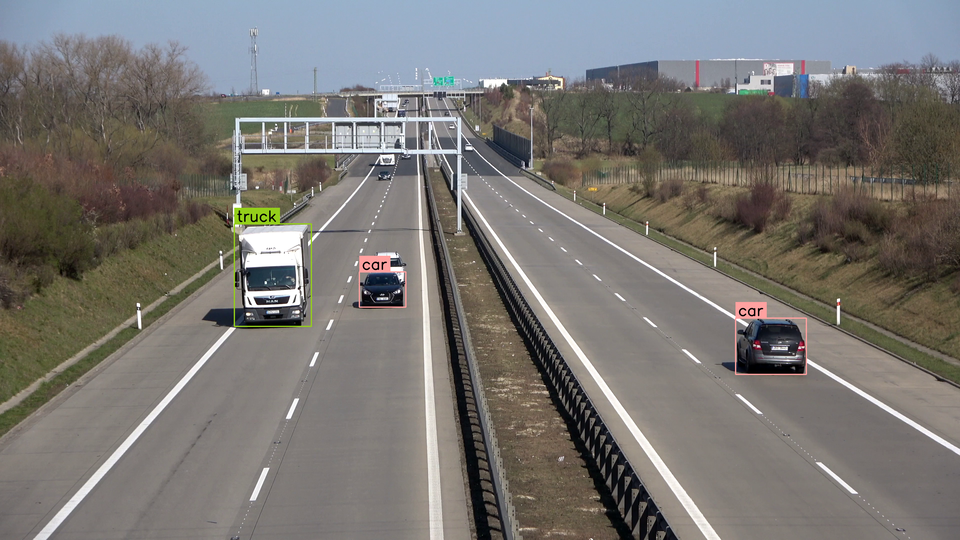
Use BoxAnnotator and LabelAnnotator to draw bounding boxes and class labels.
Annotation needs both the source image and its detections; multiple annotators
can add their overlays to the same image.
from ml_pipes.core import Pipeline
from ml_pipes.standard import Recall, Select, Store
from ml_pipes.supervision import BoxAnnotator, Detections, ImageToArray, LabelAnnotator
from ml_pipes.supervision.inference import RoboflowInference
from ml_pipes.vision import Decode, LoadFile
pipeline = Pipeline(
[
LoadFile(),
Decode(),
ImageToArray(),
Store("source_image"),
RoboflowInference(model_id="rfdetr-small"),
Select(0),
Detections.FromInference(),
Recall("source_image", prepend=True),
BoxAnnotator(),
LabelAnnotator(),
]
)
annotated_image, detections = pipeline("people-walking.jpg")
import cv2
import supervision as sv
from inference import get_model

model = get_model(model_id="rfdetr-small")
image = cv2.imread("people-walking.jpg")
results = model.infer(image)[0]
detections = sv.Detections.from_inference(results)
box_annotator = sv.BoxAnnotator()
label_annotator = sv.LabelAnnotator()
annotated_image = box_annotator.annotate(
scene=image, detections=detections)
annotated_image = label_annotator.annotate(
scene=annotated_image, detections=detections)
Display Custom Labels
By default, sv.LabelAnnotator
uses detections.data["class_name"], then class IDs, then detection indices.
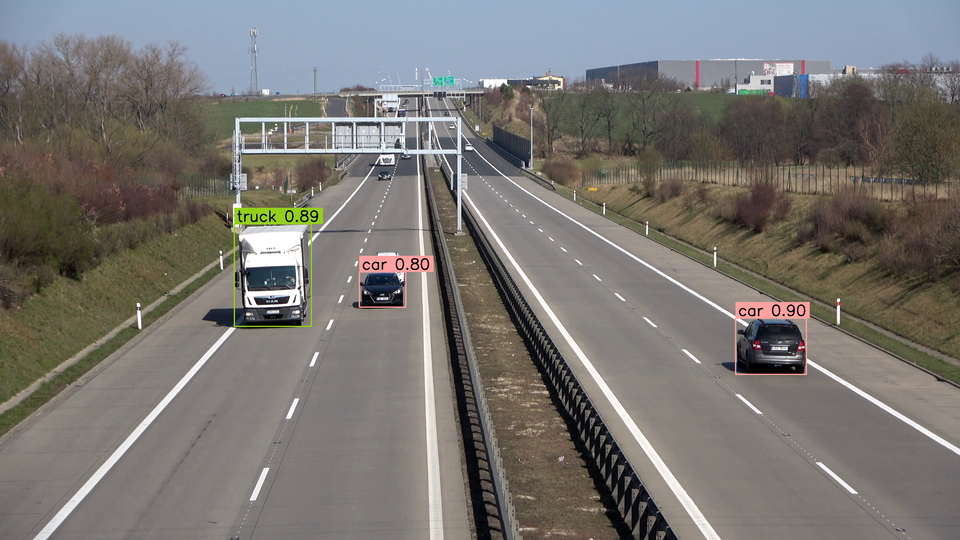
Custom labels can include confidence scores or other detection data. The
examples below add class names and confidence to each detection's label.
from ml_pipes.core import Pipeline
from ml_pipes.standard import Recall, Select, Store
from ml_pipes.supervision import BoxAnnotator, Detections, ImageToArray, LabelAnnotator
from ml_pipes.supervision.inference import RoboflowInference
from ml_pipes.vision import Decode, LoadFile

pipeline = Pipeline(
    [
        LoadFile(),
        Decode(),
        ImageToArray(),
        Store("source_image"),
        RoboflowInference(model_id="rfdetr-small"),
        Select(0),
        Detections.FromInference(),
        Recall("source_image", prepend=True),
        BoxAnnotator(),
        LabelAnnotator(show_class=True, show_confidence=True),
    ]
)

annotated_image, detections = pipeline("people-walking.jpg")
import cv2
import supervision as sv
from inference import get_model

model = get_model(model_id="rfdetr-small")
image = cv2.imread("people-walking.jpg")
results = model.infer(image)[0]
detections = sv.Detections.from_inference(results)

box_annotator = sv.BoxAnnotator()
label_annotator = sv.LabelAnnotator()

labels = [
    f"{class_name} {confidence:.2f}"
    for class_name, confidence
    in zip(detections['class_name'], detections.confidence)
]

annotated_image = box_annotator.annotate(
    scene=image, detections=detections)
annotated_image = label_annotator.annotate(
    scene=annotated_image, detections=detections, labels=labels)
Annotate Image with Segmentations
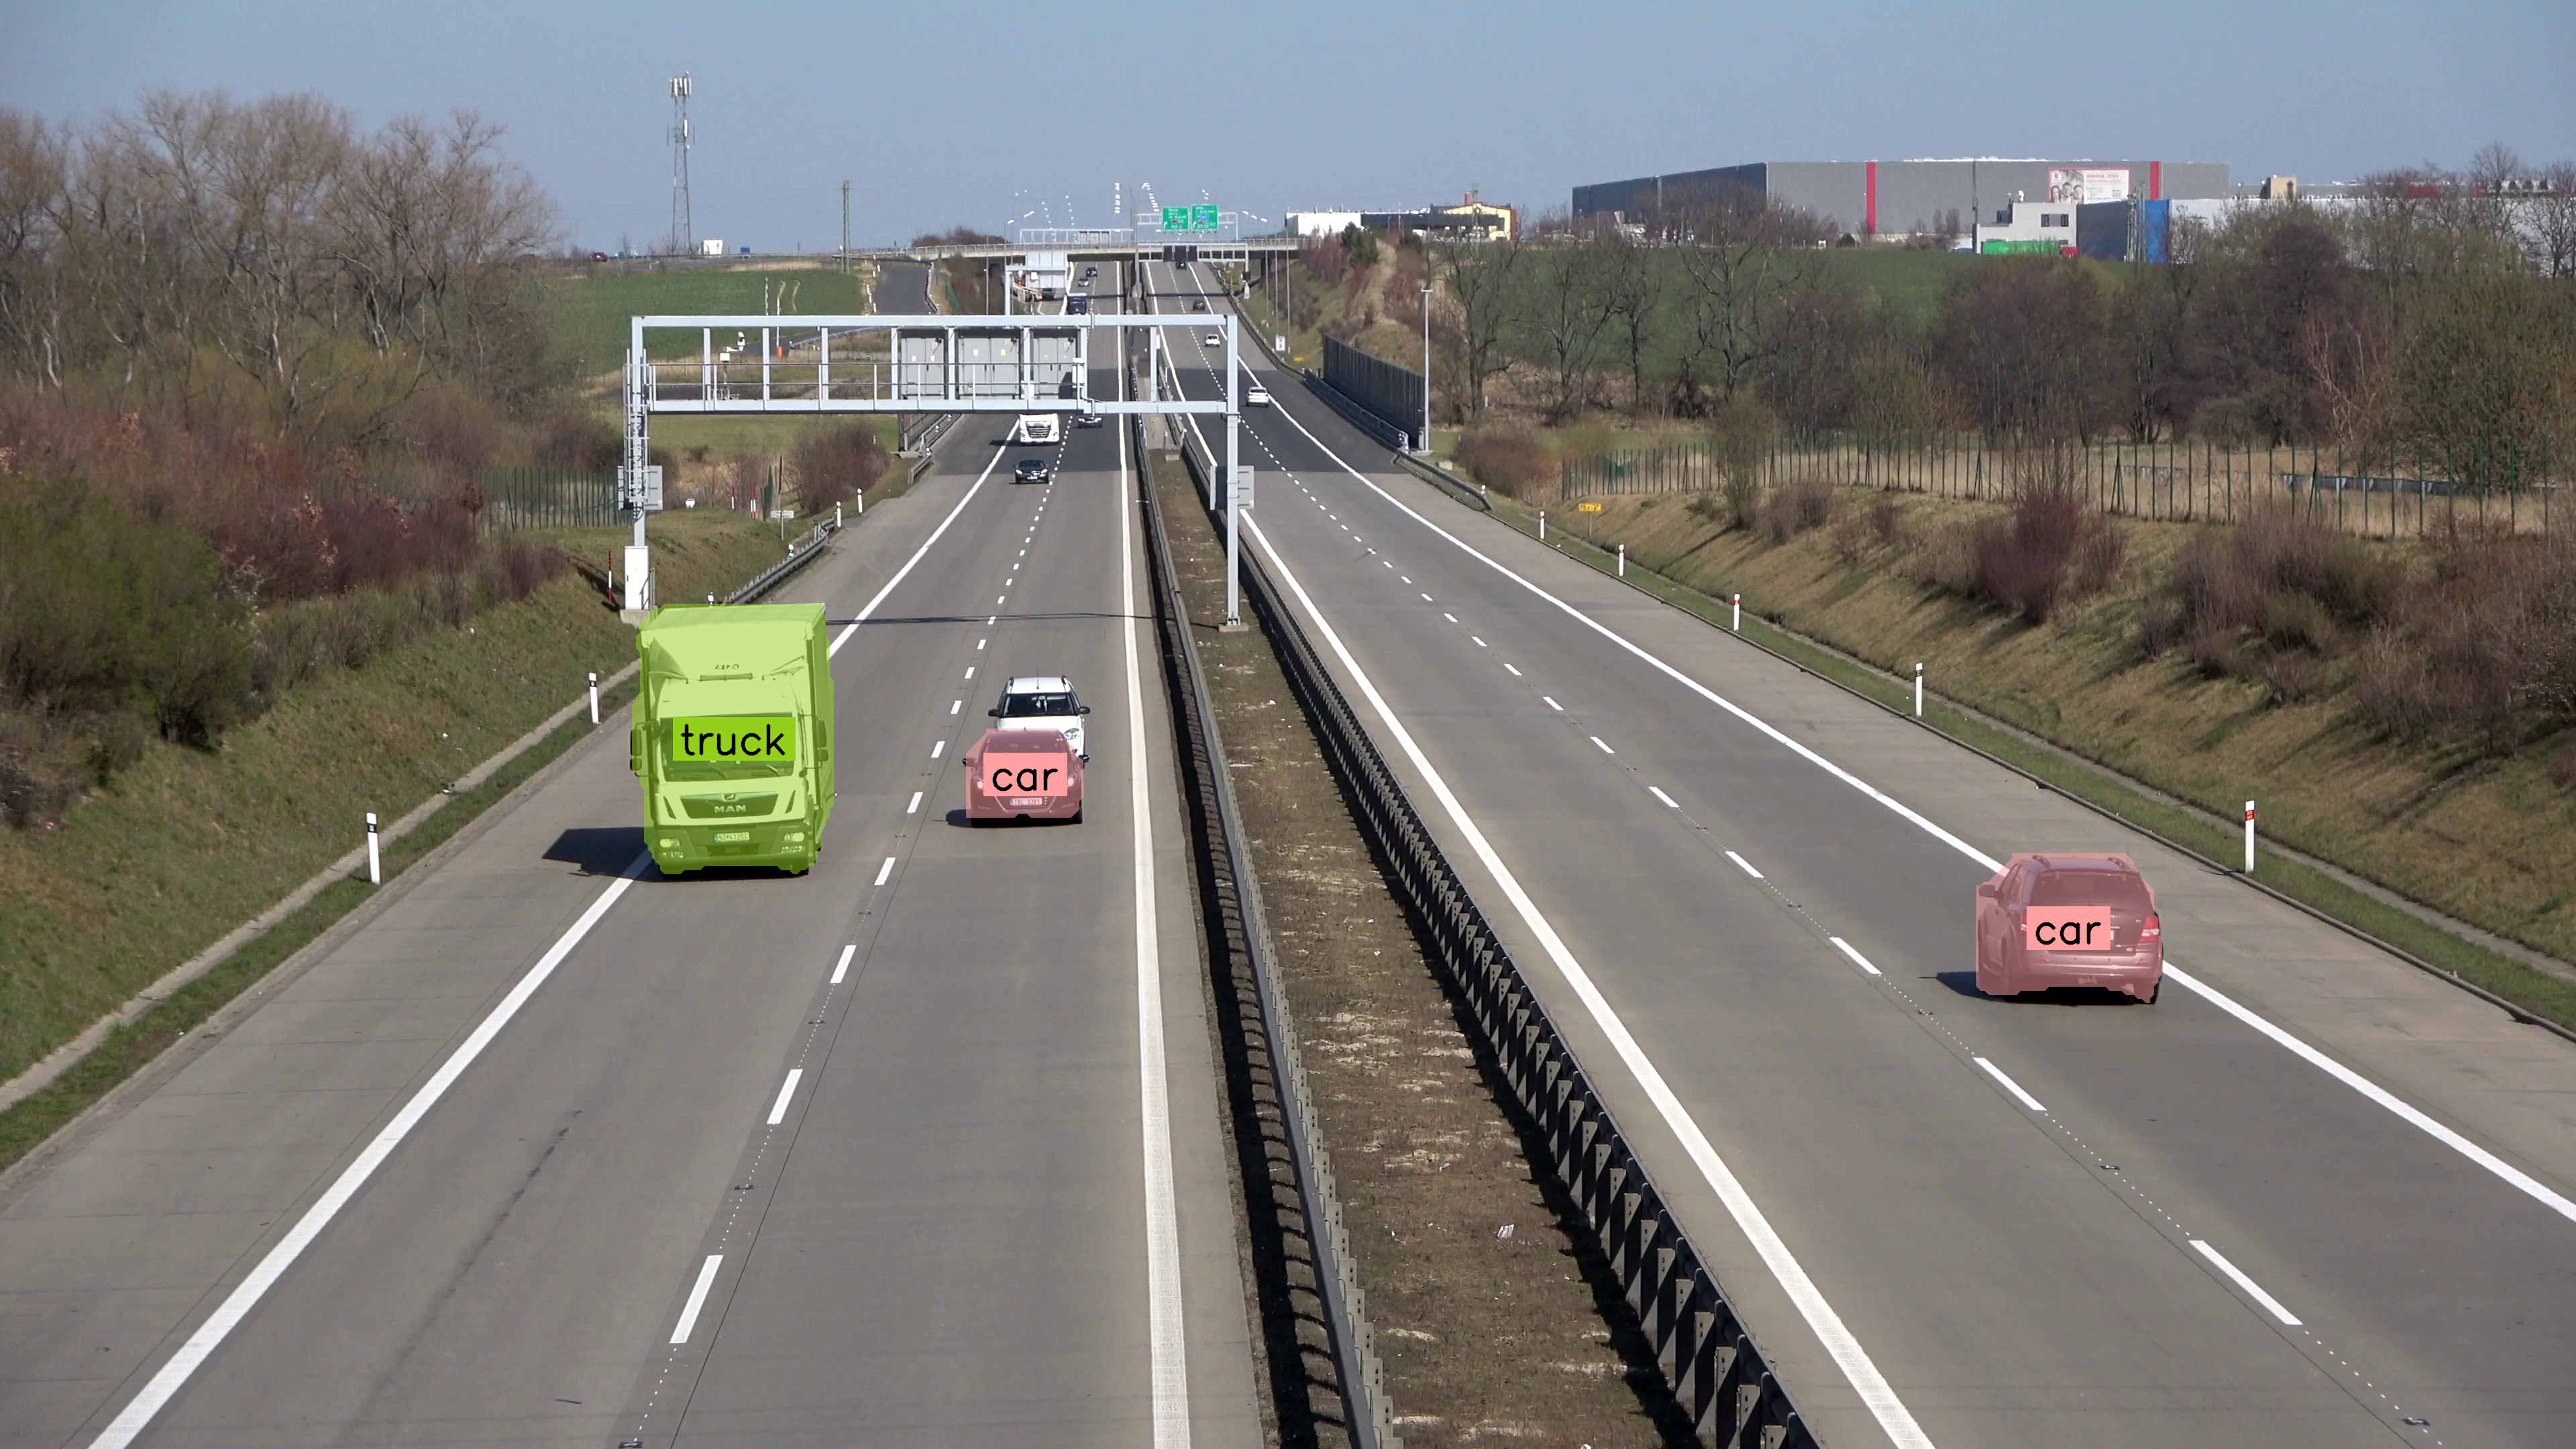
For segmentation results, use MaskAnnotator instead of BoxAnnotator to draw
masks rather than boxes. Combine both annotators if you want boxes and masks
on the same image.
import supervision as sv

from ml_pipes.core import Pipeline
from ml_pipes.standard import Recall, Select, Store
from ml_pipes.supervision import Detections, ImageToArray, LabelAnnotator, MaskAnnotator, PlotImage
from ml_pipes.supervision.inference import RoboflowInference
from ml_pipes.vision import Decode, LoadFile

pipeline = Pipeline(
    [
        LoadFile(),
        Decode(),
        ImageToArray(),
        Store("source_image"),
        RoboflowInference(model_id="rfdetr-seg-small"),
        Select(0),
        Detections.FromInference(),
        Recall("source_image", prepend=True),
        MaskAnnotator(),
        LabelAnnotator(text_position=sv.Position.CENTER_OF_MASS),
        PlotImage(at=0),
    ]
)

annotated_image, detections = pipeline("people-walking.jpg")
import cv2
import supervision as sv
from inference import get_model

model = get_model(model_id="rfdetr-seg-small")
image = cv2.imread("people-walking.jpg")
results = model.infer(image)[0]
detections = sv.Detections.from_inference(results)

mask_annotator = sv.MaskAnnotator()
label_annotator = sv.LabelAnnotator(text_position=sv.Position.CENTER_OF_MASS)

annotated_image = mask_annotator.annotate(
    scene=image,
    detections=detections,
)
annotated_image = label_annotator.annotate(
    scene=annotated_image,
    detections=detections,
)
sv.plot_image(annotated_image)
Compact Masks
For segmentation, replace the conversion stage with
Detections.FromInference(compact_masks=True). Supervision's sv.CompactMask
stores cropped, encoded masks instead of full-image dense arrays;
MaskAnnotator and Detections.Stitch() accept these masks.
Compact conversion crops masks to detector bounding boxes, dropping pixels
outside them. Keep the default compact_masks=False to preserve those pixels.
See the upstream compact-mask guide
for formats, conversion, and performance details.
Inspect the Pipeline
Use Pipeline.inspect() to capture the value at every operator boundary
without changing the pipeline's final output. The inspection renderer turns
that captured run into a shareable HTML report.
from ml_pipes.inspection import PipelineInspector

inspection = pipeline.inspect("vehicles_frame.jpg")
PipelineInspector().save(inspection, "inspection.html")
The report below captures the Detect and Annotate pipeline on a frame from the vehicle video used in the line-crossing example.
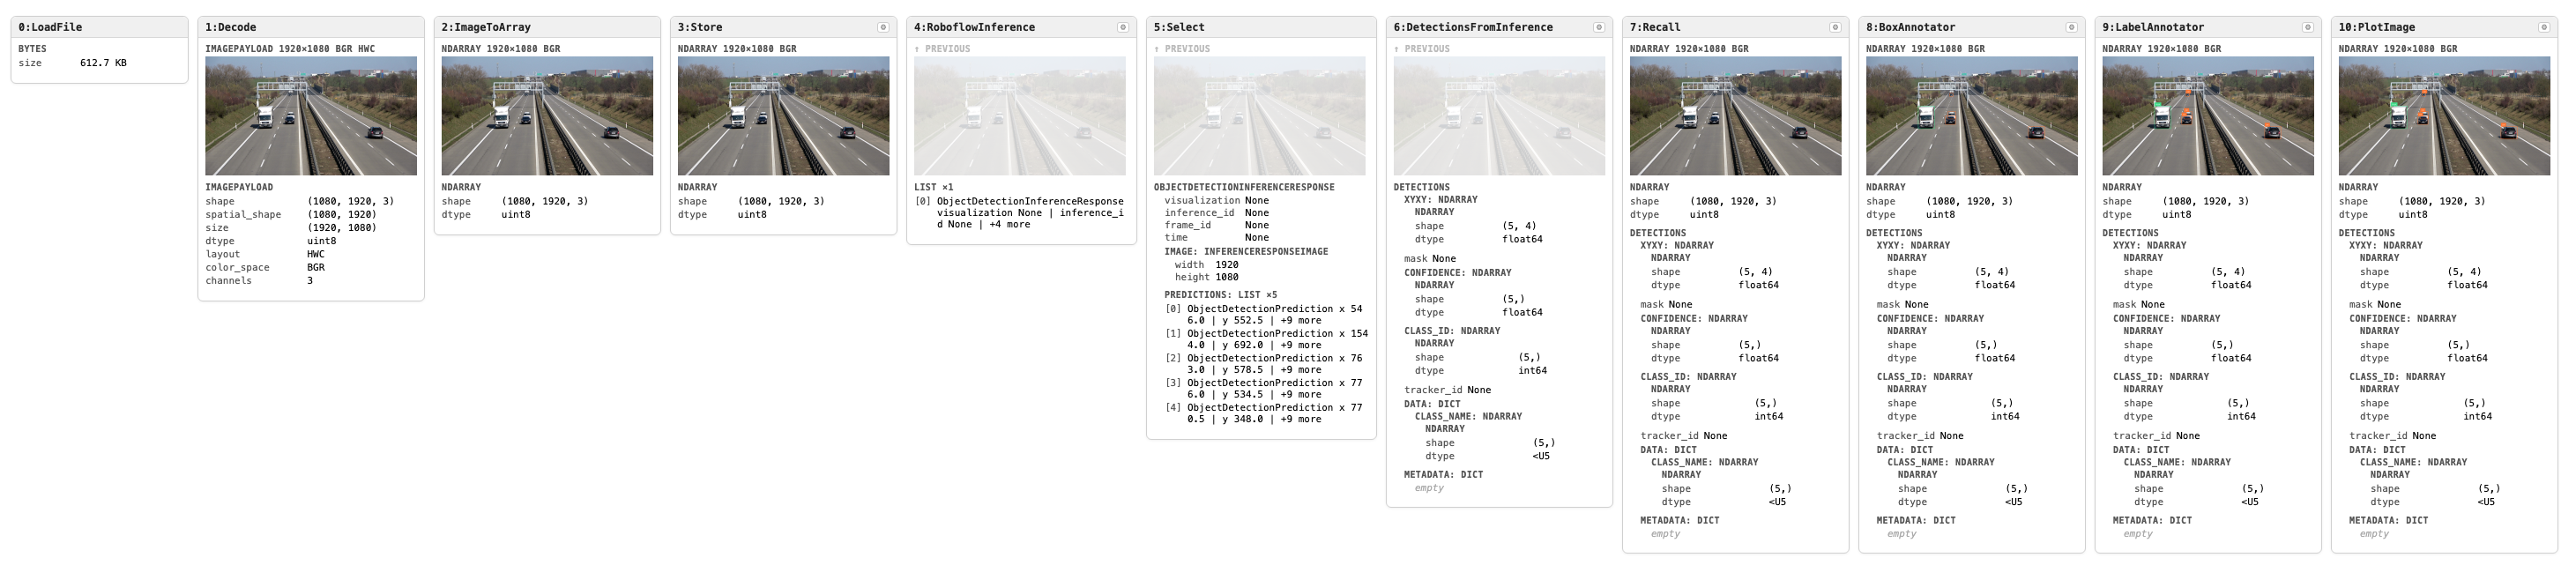
Click the image to open the interactive inspection report.
Authors
- Piotr Skalski — Computer Vision Engineer, Roboflow
- Borda — Open Source Engineer, Roboflow